Typescript vs JavaScript

https://stackify.com/typescript-vs-javascript-migrate/

Given that we have been working with Typescript I wanted to find a blog post that compare and contrasts these languages to grasp a better understanding of their benefits. First we should define what the languages are. Typescript is an open source “syntactic superset” of JavaScript that compiles to JavaScript. Typescript offers the developer a static type checking for JavaScript to be compiled. Where JavaScript is almost the opposite of this; JavaScript uses type less variables that can be assigned any data. That is a basic understanding of the two languages that are based from Java.

From here lets discus the benefits of using Typescript language as stated above Typescript allows for the assignment of static types. This prevents complications like data being changed if not meant to, or faulty variable assignment to begin with.

An Example:

Typescript when a is an int:  a = 1;

Javascript when a is typeless: a = “1”

The thing is that JavaScript would allow you to assign the value to string 1, but Typescript would not allow you to make the same assignment. Additionally Typescript also adds other features to JavaScript like: Interfaces, Generics, Namespaces, Null Checking, and Access Modifiers.

Interestingly the blog talks about how type values are not the only reason to use typescript, or at least the exclusive reason. When deciding to use typescript the blog offers this advice:

TypeScript

  • Prefer Compile Time Type Checking: It is entirely possible to perform runtime type verification using vanilla JavaScript. However, this introduces additional runtime overhead that could be avoided by performing compile-time validation
  • Working with a New Library or Framework: Let’s suppose you’re taking up React for a new project. You are not familiar with React’s APIs, but since they offer type definitions, you can get intellisense that will help you navigate and discover the new interfaces.
  • Large Projects or Multiple Developers: TypeScript makes the most sense when working on large projects or you have several developers working together. Using TypeScript’s interfaces and access modifiers can be invaluable in communicating APIs (which members of a class are available for consumption).

JavaScript

  • Build Tools Required: TypeScript necessitates a build step to produce the final JavaScript to be executed. However, it is becoming increasingly rare to develop JavaScript applications without build tools of any kind.
  • Small Projects: TypeScript may be overkill for small teams or projects with a small code surface area.
  • Strong Testing Workflow: If you have a strong JavaScript team who is already implementing test-driven development, switching to TypeScript may not give you enough to make it worth the associated costs.
  • Added Dependencies: In order to use libraries with TS, you will need their type definitions. Every type definition means an extra npm package. By depending on these extra packages you are accepting the risk that these may go un-maintained or may be incorrect. If you choose not to import the type definitions, you are going to lose much of the TS benefit. Note that the DefinitelyTyped project exists to mitigate these risks. The more popular a library is, the more likely the type definitions are to be maintained for the foreseeable future.
  • Framework Unsupported: If your framework of choice does not support TS, such as EmberJS (although this is planned and is the language of choice for Glimmer), then you may be unable to take advantage of its features.

The author Jared Nance goes on to say that Typescript isn’t the best tool out there for coding, but presents the information as best as possible. When considering to use Typescript or JavaScript the suggested reasons above may be good guide lines in making that choice.

From the blog CS@Worcester – Computing Finn by computingfinn and used with permission of the author. All other rights reserved by the author.
Useful Wireframes


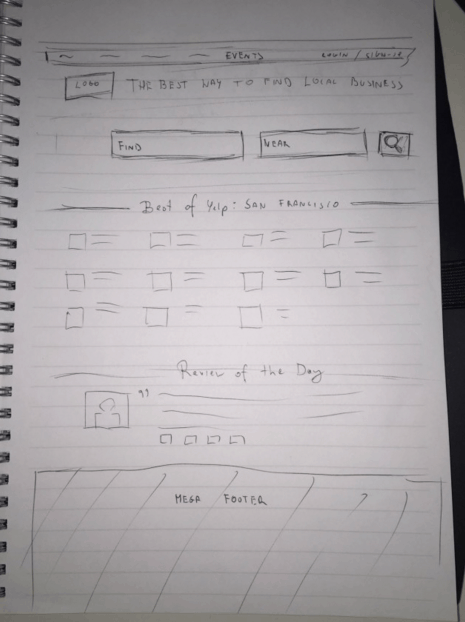
In this weeks blog I’m going to step back and go to the basics of design and take a look at effective wireframe design and implementation. Wireframes are the backbone of a project and help the team of developers show their ideas on layouts, visual hierarchies, content, and information architecture. Wireframes use placeholders to represent the content that will come later in the development process. Building wireframes has a variety of benefits such as knowing where everything will go before implementing the exact details, the ability to create foundations early on in the process, and the wireframes simplicity allows for creativity and experimentation.

One of the best things about wireframes is the availability and ease of making one.  While they do have specialized wireframing tools and image editors a wireframe can be simply made with a piece of paper and a pen.

1

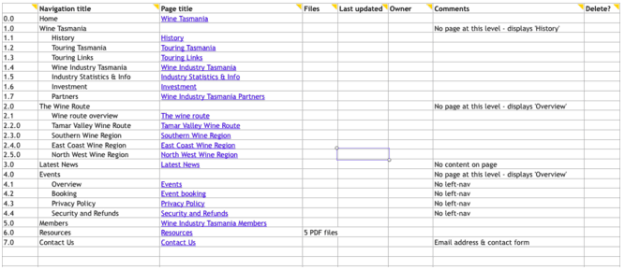
The first step in making a wireframe the article suggests is to create a content inventory. The content inventory allows the developer to get all their materials in one place before building. Inventories are usually spreadsheets that list all the separate content that will be including on the page, this can include things such as a list of URLs with descriptions. The content should be organized by topic and should be allocated to the correct page. Next, it is recommended to create a visual hierarchy by marking each item by importance as primary or secondary.

2

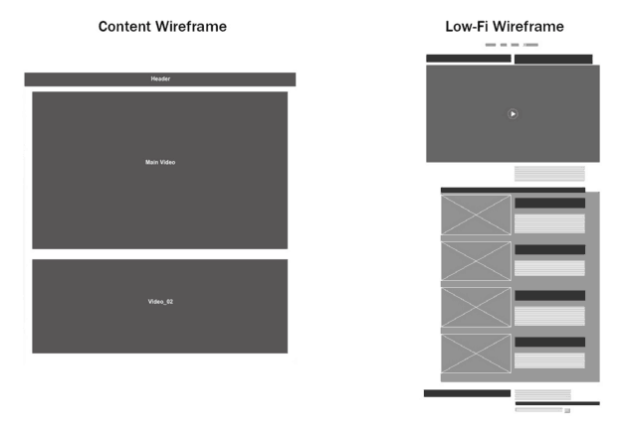
We can then begin to make the wireframe itself. We start by making a content wireframe which will allow us to place all our content and prioritize the essential elements. It is recommended to start with a mobile-first approach when making an application for this reason, as you can always scale upwards if needed. Once all the content is generally in place, it is time to “sculpt” the wireframe by designating where individual links and icons will go and setting space and sizes for images. It is then recommended to turn the wireframe into a lo-fi prototype so that testing can begin. Certain platforms allow drag and drop interactivity which helps designate usability issues early on.

3

This method allows for rapid prototyping which involves creating prototypes quickly, testing them, and then incorporating the feedback into the next build. The design refines as you go instead of testing everything at once. This leads to much more efficient wireframes and overall applications.

From the blog CS@Worcester – Jarrett's Computer Science Blog by stonecsblog and used with permission of the author. All other rights reserved by the author.
Journey into Schematics-An Introduction

As I take another step towards my journey in software C.D.A. I dive into an Introduction on Angular Schematics. This weeks blog I will be summarizing the blog “Schematics – An Introduction” by Hans.

This blog gives an introduction to Schematics and what it is. It list the goals of using a Schematic design. It shares how to understand schematics and how to create your first schematic. It tells you about the Schematics Collection and how to use it. Where it goes over the files such as Rules and Trees.

  • “ARuleis a function that takes a Tree and returns another Tree"
  • “A Tree contains the files that your schematics should be applied on”

The blog also shows you how to run your new Schematics. It also mention that when in debug mode you will not be able to create a file to the file system because “schematics tool is in debug mode when using a path as the collection it should use”, but also “the default is also to run in dry run mode, which prevents the tool from actually creating files.” that can be changed by changing the default argument. The blog has an example on how to do so. It then explains that a great advantage of Schematics is that calling another schematic is very easy and having them compose together is just as easy as well. It also mention that “the best usage of Schematics for your users is currently through the Angular CLI.”

This is a well written blog that gave good examples that are understandable and on point. I found the idea of schematics very interesting and also useful because it is capable of creating new component or updating code in order to fix and break dependency. It also provides ease of use and development when working with web application in particularly Angular. This has made me consider using Schematic since it is very beneficial to do so. This blog has thought me a new topic not really covered in class. I can honestly say that there is not a single thing I disagree on with the blog. For more on the blog and its example check it out by just clicking on the title of the blog, it will link you to it. Thank you for your time. This has been YessyMer in the World Of Computer Science, until next time.

From the blog cs@Worcester – YessyMer In the world of Computer Science by yesmercedes and used with permission of the author. All other rights reserved by the author.

Journey into Angular Schematics: Unit Testing

As I take another step towards Software Quality Assurance Testing. I dive into Angular schematics for unit testing. The blog that I read that covers this topic was “Angular Schematics: Unit Testing by Jonathan Campos. This blog covers the basic of unit testing code, mimicking an application environment, adding a test, asserting on files created, and asserting on content created. All in order to discuss and show the methods of creating a unit test for an Angular Schematics. This is a well written blog that gave good examples that are understandable and on point. The blog has thought me that angular projects should and can be tested. Which would be something I will be practicing on any of my future angular project. In the following paragraph I will briefly summarize what was cover in the blog excluding the examples.

The basic unit testing code is just explaining the basic of unit testing, and it being the starting point step. It then goes on and shows an example of how a file should look like when the schematics generator generates it. That file does not do much it just “run the schematic in a silo and asserts that the output is an empty file tree”.  It goes on to explain that to test your code accurately you must go further more by mimicking the application environment. This is done by adding more to the unit test so it can reflect the actual environment where the code will be running. To do this some of the Angular Schematics must be run in order “to build up the Angular project workplace”. This can be done by adding code to the Angular Schematics that specifies the set option it should run with. But before anything is run an application file tree must be created. That way before each test the code will run and create the Angular project workspace. Once that is done you can add test to the testing environment. The blogger gives example of what happens in the test by creating three different testing scenario. First he test that there was any error thrown because in that test he is testing a Schematic being ran without an Angular project tree setup. Second he is testing what happens when a Schematic is ran without the required parameters. Third he is testing that everything is setup properly. Once the test were ready the next step was asserting the test for specific values that would be for either asserting on files created or asserting on content created. He goes on and explain a little more in the blog and provides examples.

For more on the blog and its example check it out by just clicking on the title of the blog, it will link you to it. Thank you for your time. This has been YessyMer in the World Of Computer Science, until next time.

From the blog cs@Worcester – YessyMer In the world of Computer Science by yesmercedes and used with permission of the author. All other rights reserved by the author.

Premature optimization

I am writing in response to the blog post at https://9clouds.com/blog/premature-optimization-the-root-of-all-evil/ titled “Premature Optimization: The Root of All Evil”.

Premature optimization is about focusing on making sure the code will be able to run as fast as possible before anything actually works yet. It is time consuming and, by definition, “premature”, so it is not a good thing to do. The blog post quotes Donald Knuth who said “Premature optimization is the root of all evil.” For sizable projects, premature optimization is practically procrastination. It is about making sure that the program works well in theory before making sure that it works at all. The blost post seems to be referring to premature optimization on the scale of businesses, where I am only considering the effect on individual programs and projects, but the effects are the same. It makes more sense to finish something that works and then improve it than it does to improve it first and then finish it.

I have done a lot of premature optimization on small projects, and it certainly does take up a lot of time. I tend to do it just because it is interesting, though, to try to come up with such an implementation that performs optimally. It is a secondary challenge that puts off the original task. If it becomes tedious or starts to seem wasteful then I just write something that works and move on to the next part, and if it matters or makes a difference, and it never does, I can just look into how to make things faster again. The idea of actually producing something in a professional sense and becoming caught up in the performance details on a small scale before the rest of the product is finished definitely seems like it would be a waste of time. Premature optimization requires making predictions of how things are going to work after they are made, and devising a plan to make things fit together smoothly before the things even exist yet. It makes much more sense to make the things first, and then make them work together better afterwards.

From the blog cs-wsu – klapointe blog by klapointe2 and used with permission of the author. All other rights reserved by the author.

Black/White box testing

I am writing in response to the blog post at https://www.guru99.com/back-box-vs-white-box-testing.html titled “Black Box Testing Vs. White Box Testing: Key Differences”.

Black box testing and white box testing are topics that we have covered in the CS 443 software quality assurance and testing class. Black box testing involves testing from the perspective of a user, who does not have access to the code, and thus the testing is done without referring to the code. Instead, the behavior is tested directly by checking inputs against expected outputs. White box testing involves code coverage and testing different branches and paths of code based on the code itself and not a pre-defined specification for the behavior to meet.

The blog post provides a table of comparisons between black box testing and white box testing. Most of the points are that black box testing is done without access to the code and white box testing focuses on the code. One of the points made is that black box testing is not good for testing algorithms. This makes a lot of sense, and for certain algorithms, black box testing would be impossible to do. Black box testing requires some specification for the behavior of the program to meet, and that specification is supposed to cover everything that might go wrong with the program. This is fine when the program is made up of a set of conditional branches, but something more intricate like a computational geometry or machine learning algorithm would be impossible to test every case for because the number of different paths the code can take is on a completely different scale. White box testing in this case would be the only way to check that the algorithm will work, and that is by proving that it works. The only way black box testing could prove correct behavior would be with an exhaustive proof.

White box testing is not necessarily as easy or convenient as black box testing because it requires understanding and analyzing the code instead of just running it and seeing what happens. In some cases, though, it is necessary to use.

From the blog CS@Worcester – klapointe blog by klapointe2 and used with permission of the author. All other rights reserved by the author.

AntiPatterns: Golden Hammer

Another day, another blog post about a concept from Sourcemaking.com, this time on the Golden Hammer AntiPattern.

Software Development is a field that requires continuous learning throughout your entire career. With the sheer amount of tools at your disposal, it can be daunting to try to expand your skillset. However, knowing how to utilize as many tools as possible is important to help make an effective and well-rounded developer. Not only that, being brave enough to drop the tried and true way of doing things for newer, more effective solutions is an important soft skill to have as a team.

We’ve all heard of the expression, “If all you have is a hammer, everything looks like a nail.”, and that’s the exact origin this AntiPattern. When a team fails to develop their knowledge and expand their skillset, they often fall back on the same process that they’ve used in the past. Sometimes, a significant financial investment has been made into training the team to use a specific product, and so they don’t want to let that methodology go to waste. That’s fine, except for the fact that there is a unique way to approach nearly every new problem that developers come across. Reusing old system design is a sure fire way to cause more problems than necessary for the development process.

There are countless issues with this approach — it’s like trying to fit a square peg in a round hole. In a way, teams will end up warping the problem in order to make their solution work, as opposed to designing a good solution for the problem. It’s self limiting too, because teams will only end up choosing problems that they feel comfortable with, relating back to approaches they have taken in the past. Not only this, but if the Golden Hammer is a particular product or tool made by another company, then the team can find themselves at the mercy of that company to continue support for that product.

Not only does this AntiPattern require a tremendous amount of refactoring (usually, a complete reworking of the product is necessary), it requires a change in the philosophy of the developer(s). Each and every member of the team needs to be focused on expanding their knowledge of shifting trends in technology, and there must be an emphasis on the exploration of new tools in the workplace with some leeway in deadlines as a result.

From the blog CS@Worcester – James Blash by jwblash and used with permission of the author. All other rights reserved by the author.

AntiPatterns: Spaghetti Code

Many AntiPatterns seem to arise when code structure is ignored and foundational concepts like those of OOPs are forgotten. Spaghetti Code is perhaps the most common and widespread of these, since it can come about so easily in nearly any program regardless of the language or paradigm. In a general sense, it is unstructured code that is difficult to read, edit, or use.

Spaghetti Code involves a very cluttered, messy design (or lack thereof). There are many moving parts which seem disorganized and generally readability is extremely, low even for the original developer. It’s much more easily found in procedural paradigms as Object Oriented paradigms were made partially to avoid this problem in particular. If Spaghetti code is found in an Object Oriented system, the structure often reflects that of a procedural program.

I’ve written about The God Class before, which is a concept that stems from similar errors, except in a slightly different form. Spaghetti Code differs from this in that the God Class has one central core class that makes extending and modifying anything more of a challenge than is necessary. Spaghetti Code generally has several large classes which run in a single, multistage process. Sometimes this kind of messy code can be found within other AntiPatterns, such as Lava Flow. Dead ends of routes taken with old projects can result in a jumbled mess of irrelevant code that is hanging around for no reason other than it is difficult to read.

So what can we do about it? Well, like many other AntiPatterns, the best solution is to take a preventative approach. Make sure that a clearly defined structure for the program is outlined before starting to develop. Make sure that when modifying the existing code, the developer adheres to the structure in place. If you’ve found yourself in a position where you need to refactor Spaghetti Code, it could potentially be a case of diminishing returns where trying to “fix” the program is more difficult than rebuilding it from the ground up. This is a massive waste of development time and money, since if a clear goal were in place to begin with the problem could have been avoided all together.

At the end of the day, a clear vision and game plan for the software you’re writing is the most important piece of development. Without a path to follow, problems become difficult to solve and solutions become difficult to implement — especially when developing a large scale software system.

From the blog CS@Worcester – James Blash by jwblash and used with permission of the author. All other rights reserved by the author.

Is Your Interface Two-Faced?

CS SERIES (11).pngWhen coding, users always have to be conscious about the way their code may be implemented or used in the future by different services leading to potential misuse. After reading Code Health: Make Interfaces Hard to Misuse by Marek Kiszkis, it made me think about how important communication between testing code is.

I found this content useful because Kiszkis featured some examples that can show how an interface could be misused easily. The examples included:

  • Requiring callers to call an initialization function
  • Requiring callers to perform custom cleanup
  • Allowing code paths that create objects without required parameters
  • Allowing parameters for which only some values are valid, especially if it is possible to use a more appropriate type

Sam CS (17)It is also good to remember that at the end of the day, code should be defensive but not too defensive to the point that complexity is increased and performance overall is reduced. Kiszkis says “it is not always practical to have a foolproof interface” because there will be situations where some requirements are things that cannot be expressed in an interface.

After seeing so much content based on being careful about what you code it is surprising how this article says it is not necessary to plan too hard. I kind of understand why Kiszkis would say this but personally, I kind of disagree with this. The reason why I disagree is because if someone does happen to end up with more time to work on something than expected and they know it will make something more efficient, then why not go for it?

Overall, I appreciated what was shared in this article in terms of encouraging users to try and see issues that can arise with their code when it comes to interfaces. The main takeaway for me is that if something is brought up, or triggered by undefined behavior, a user should try and make it impossible for this to happen. A way of doing so is by adding things where necessary, like certain slots in his example. It does not have to be too specific but detailed enough so that it covers different aspects, similar to how we try to prepare for everything when it comes to equivalence class testing.


Article: https://testing.googleblog.com/2018/07/code-health-make-interfaces-hard-to.html


From the blog CS@Worcester by samanthatran and used with permission of the author. All other rights reserved by the author.

New Instances in JUnit

Martin Fowler’s Blog is an amazing resource for someone breaking into the field of Software Development — his blog posts are extremely easy to read and are very educational. Even older content is still relevant and helpful to read through, like this article on the reasoning and design decision behind JUnit tests creating new instances for each test. As someone who has only a bit of experience writing my own Unit Tests, this was pretty eye-opening.

So why does JUnit create a new instance for each test, and what does that even mean? Each time you run a test, a new instance of each object used in the test is created. This means that in one test, if you create an object or assign a value, that change will not carry over into any other tests. The idea behind this is called isolation, and although it may seem counterproductive, it is extremely important. It ensures that no test should ever do something that would cause another test to fail.

So what exactly makes isolation so important? The point of Unit testing is to bend and stress the basic structure of the source code. If all tests were relying on a shared state which was dynamically changed between one another, each would leave behind data that would impact the other tests. You’d end up testing not just the source code, but you’d also be dancing around the different tests you had already written. If each test weren’t isolated, it would make the main objective — testing the product — significantly more complex.

JUnit in particular provides functionality to support this isolation and make the job of the tester easier — things like the setUp method. If you want each test method to create an Array with 5 elements, you would place that in the setUp method for it to be run prior to each test as opposed to having to rewrite that piece of code for each test you have. This helps keep each test isolated, whilst still providing every test with a shared base state from which to run.

If you’re like me, you had encountered this problem while tinkering around with JUnit and kind of accepted it without questioning the purpose behind it. It’s intuitive and makes sense that each test should be isolated from the others, but it is also important to ask “Why?” or “What would change if this were different?”. It gives insight into the JUnit framework, and helps make a more effective tester.

From the blog CS@Worcester – James Blash by jwblash and used with permission of the author. All other rights reserved by the author.