The Strategy Pattern

Today’s blog post is about the Strategy design pattern. I found a blog on the Strategy pattern called “Design Patterns: Strategy”. This blog talks about the pattern, what it is, and how to implement it. The Strategy pattern is a way to get classes to interact nicely with each other, and keep code somewhat clean and manageable. The author of this blog uses the video game Overwatch as an example to showcase how the Strategy pattern works. In the Overwatch game there is a superclass Player, and Player has many attributes. In this demonstration, the author labels these primary_ability, secondary_ability, and ultimate_ability. These are all subclasses to the superclass Player. This seems like a pretty simple relationship that is easy to manage, which is true until you find out that there are 21 forms of playable characters. This, in essence, means that now all of those classes get multiplied 21 times. This makes code very labor intensive and difficult to organize. There should be a way to connect each of the 21 different character classes to only one primary_ability, secondary_ability, and ultimate_ability classes; rather than write those classes out 21 times. Additionally, each of the 21 classes would have to be overriden to cater to the different character classes. To remedy this, the author creates a series of classes (or “Strategies”) to keep from having to write out the classes 21 times, uniquely each time. Now, each version of the character class can inherit the Strategies, which hold the basic methods, and tailor them to the specific character by overriding them. Then, the character gets passed to the Player class. In the end, the Player class just gets passed a character, without having to know any specifics of attributes.


I chose this article because we just finished learning about the Strategy pattern in class, and we have an assignment coming up which uses this. I want to fully understand this before I take on the assignment, because I want to do the assignment correctly. The Strategy pattern is a rather straightforward software design, but it is extremely effective. I think that this reinforced my understanding of the Strategy design, and helps me to clearly see how the classes relate to each other. Before reading this article, I had a good understanding of the pattern, but the examples presented in this article helped me really get what the Strategy pattern is all about. I hope that now I will be able to implement the Strategy pattern without any issues, when dealing with a parent classes that have a multitude of similar subclasses.

Here’s the link to the blog:

https://www.madetech.com/blog/design-patterns-strategy


From the blog CS@Worcester – The Average CS Student by Nathan Posterro and used with permission of the author. All other rights reserved by the author.

Software Construction, Design, and Architecture: Post 2

Hello Reader. I’m back here again, ready to cover another day in class.
So, it turns out I’m going to have to modify this and some of my past posts, so that they are grade-able for the class. Otherwise, my posts are still gonna follow the same sort of format, where I just candidly cover everything going on in class, as much as I can.

It’ll include a reflection on the material and I’ll be answering  some questions put forth by my Professor, Dr. Wurst. As for right now, I’m preparing to take on whatever we have to get done for today.


Come to think of it, there is a word count restriction on the posts for the class. I will make separate posts for those questions, specifically.


We are talking about UML Class diagrams today. They are the most commonly used UML diagram. We use these diagrams to put on paper what makes up a software program, from the classes set up within the program, to details about said classes, and then the relationships between classes.


First, you have the class name. Within a box divided into three boxes horizontally, the top box is the class name. Then, you have their properties, second box. Finally, the last box contains methods that the class/other classes (depending on its visibility) can call on to use.


Sorry I havent uploaded this, not going to add onto anymore as of now but just uploading what I wrote.

From the blog CS@Worcester – Sean Raleigh's CS Blog by sraleigh62 and used with permission of the author. All other rights reserved by the author.

WSU Blog #3 for CS-443

From the blog Rick W Phillips - CS@Worcester by rickwphillips and used with permission of the author. All other rights reserved by the author.
Tips for clean coding in java

I am required to read quite a bit of code written by other people, and over the years I’ve found that there are some problems that tend to recur again and again. The idea with this blog entry is to write up some tips , in the hope that it can help people out there who struggle to write clean code.

These are the tips for clean coding or good coding.


Keep classes small

So far you’ve created a few classes. After generating getter/setter pairs for even the small number (by the standards of a real-world Java class) of attributes, the Person class has 150 lines of code. At that size, Person is a small class. It’s not uncommon (and it’s unfortunate) to see classes with 50 or 100 methods and a thousand lines or more of source. Some classes might be that large out of necessity, but most likely they need to be refactored. Refactoring is changing the design of existing code without changing its results. I recommend that you follow this best practice.

In general, a class represents a conceptual entity in your application, and a class’s size should reflect only the functionality to do whatever that entity needs to do. Keep your classes tightly focused to do a small number of things and do them well.

Keep only the methods that you need. If you need several helper methods that do essentially the same thing but take different parameters (such as the printAudit() method), that’s a fine choice. But be sure to limit the list of methods to what you need, and no more.

Name methods carefully

A good coding pattern when it comes to method names is the intention-revealing method-names pattern. This pattern is easiest to understand with a simple example. Which of the following method names is easier to decipher at a glance?

  • a()
  • computeInterest()

The answer should be obvious, yet for some reason, programmers have a tendency to give methods (and variables, for that matter) small, abbreviated names. Certainly, a ridiculously long name can be inconvenient, but a name that conveys what a method does needn’t be ridiculously long. Six months after you write a bunch of code, you might not remember what you meant to do with a method called compInt(), but it’s obvious that a method called computeInterest(), well, probably computes interest.


Omit needless code!

It’s quite common to find code that’s commented out, but still hanging around. This is mainly bad because it bloats the code unnecessarily. People seem to do this because they want to have the possibility to bring the code back, either because they are writing an alternative they are not sure about, because they don’t dare to delete it. However, in nearly all cases there is no real reason to keep such code around. You should be using version control, and that means you could always find any deleted code again.

Also, since this code is no longer compiled or executed there is no real difference between commenting it out or deleting it. You’ve still made the change. The difference is that now it’s quite likely that this code will slowly move out of sync with the code around it, so that by the time you find you want it again it will no longer work. That actually makes the code dangerous, because it tempts you to include code without understanding what it does. (If you really understood it you could retype it quite quickly even if it was deleted.)

Of course, commenting out code while you are working on the code is fine. I do that a lot. However, I never check in code that is commented out, and whenever I find such code I delete it, without asking anyone or telling them. If they wanted the code they shouldn’t have commented it out. And it will be in the version history, anyway.

I chose this topic because i want to write code in a clean, efficient and faster way. I also chose this topic because since we will be studying it in the CS-343 class , why not learn ahead to get much more understanding on it.

Even though i knew some things about clean coding, i learned a lot. Some stuff i didn’t know where there. With these materials i have gain from other blogs or website added to my little knowledge of clean coding , i hope it will help me develop better coding in a clean, efficient and faster way.


I got the above information from this link ::: https://www.ibm.com/developerworks/library/j-perry-writing-good-java-code/index.html 

And

http://www.garshol.priv.no/blog/105.html

From the blog CS@worcester – Site Title by Derek Odame and used with permission of the author. All other rights reserved by the author.

Finding & Testing Independent Paths

Since we have been going over path testing in class this past week I decided to find a blog post relating to that material. The post I found titled, “Path Testing: Independent Paths,” is a continuation of a couple previous posts, Path Testing: The Theory & Path Testing: The Coverage, written by the same author, Jeff Nyman. In this blog post, Nyman offers an explanation into what basis path testing is as well as how to determine the number of linearly independent paths in a chunk of code.

Nyman essentially describes a linearly independent path as any unique path in  the graph that does not contain the same combinations of nodes as any other linearly independent path. He also brings up the point that even though path testing is mainly a code-based approach to testing, by assessing what the inputs and outputs should be of a certain piece of code it is still possible “to figure out and model paths.” He gives the specific example of a function that takes in arbitrary values and determines their Greatest Common Denominator. Nyman uses the following diagram to show how he is able to determine each linearly independent path:

I really liked how he was able to break down the logic in the form of processes, edges and decisions without looking at the code. I feel like sometimes when we are building our graphs strictly based on code it’s easy to get confused and forget about the underlying logic that will determine the amount of tests that are necessary to ensure our code is completely tested. It also helped me understand how basis path testing should work and how it should be implemented.

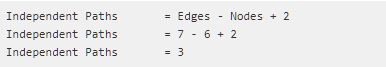
Nyman goes on by showing that he is able to calculate the number of independent paths using the above graph and the formula for cyclomatic complexity. First he points out that number of nodes is equal to the sum of the number of decisions and the number of processes, which in this case is 6. Then, by plugging numbers into cyclomatic complexity formula (V(G) = e – n +2p), Nyman was able to obtain the following results:

screenshot

Finally, Nyman ends the post by showing that the same results are obtained when going over the actual code for the Greatest Common Denominator function. He also shows that this same graph could be applicable to something like an amazon shopping cart/wishlist program. I think the biggest take-away from this post was that there is a strong relationship between cyclomatic complexity and testing which can prevent bugs through determining each linearly independent path and making sure they are producing the desired functionality.

October 1, 2017

-Caleb Pruitt


From the blog CS@Worcester – Caleb's Computer Science Blog by calebscomputerscienceblog and used with permission of the author. All other rights reserved by the author.

Post #3

Today, I am going to review and summarize Episode 283 of Software Engineering Radio.  This episode’s guest was Alexander Tarlinder, author of “Developer Testing: Building Quality into Software”.  The topics covered in this episode are quite relevant to the other posts I have done and one of those topics is specification based testing, which we have discussed in class.  I also selected this episode as the subject of this post because Alexander provides tips on how to test software effectively, both as a developer and as a tester.  The episode begins with Alexander providing an explanation as to why he wrote his book – he felt there were gaps within the software testing literature that needed to be bridged.  He claims that much of the existing literature on software testing will often focus too heavily on documentation, focus on a specific tool too much, or leave out crucial information on what to include in your test cases.  This can be hard to relate to for developers.  He defines general software testing as a process used to verify that software works, validate its functionality, detect problems within it, and prevent problems from afflicting it in the future.  He defines developer testing similarly but with the caveat that developer testing more systematically tackles the hard cases, rather than the rigorous; this is a result of developers being knowledgeable about the programming techniques implemented and the inherent bias that accompanies that.  Alexander argues that bias possessed by developers necessitates the need for additional testing to be performed by unbiased testers.  He insists that it is still necessary for developers to perform their own testing, though.  By performing testing during development, it ensures that at least a portion of testers’ workload will be a more of a “double-check”, allowing them to focus on the rigorous and unexpected cases that developers might overlook.

Alex then summarizes the main points of the discussion and provides tips on how to improve software testing.  The conversation strays a bit, so here is my summary and what I took from it:

  • Encourage developer testing – Developer testing is a necessary practice to both ensure that the finished product is of high quality and functional and to allow testers to work rigorously, which will detect and prevent any potential problems in the future.
  • Adopt an Agile development strategy – Agile development allows for rapid delivery of product and forces developers to adhere to effective working practices.
  • Write code that is testable – Consider a Develop by Contract(DbC) approach where the caller and the function being called programatically enter into a “contract” with one another.
  • Learn various techniques – Specification-based testing is a fundamental testing technique to learn, but it can sometimes lead to an approach that is too focused on where the data is partitioned, neglecting the in-between cases.

I think that this discussion contributed to my knowledge of effective development and testing practices which will help me a great deal when it comes time to implement them in the field (or an interview).

This blog post(2/9) is part of an assignment for the Fall 2017 session of CS443 @ Worcester State University.


From the blog CS@Worcester – by Ryan Marcelonis and used with permission of the author. All other rights reserved by the author.

Testing: We Shouldn’t Just Take the Happy Path

We’ve been talking about path testing in class, such as tracing the concepts and expected behaviors of our code through a series of program graphs. I wanted to learn more about the different variations of path testing, and I found a good blog regarding this topic.

EngineYard: Ben Lewis – Happy, Sad, Evil, Weird: Putting Use Case Planning Into Practice

According to Lewis, happy path testing is one that developers take when testing for expected behaviors. But Lewis states it is imperative we take unexpected actions into account as well. Rather than solely thinking like a developer, we should be also thinking like an end user; the “actors” who are going to be using our finished products.One way of evaluate a myriad of action-consequence scenarios an actor may encounter is to follow a series of testing paths:

The Sad Path
In Lewis’ blog, he describes the “sad path” as one we should follow when we are testing our code.  He suggests it gives us insight on what should happen when an “actor” does something we don’t intend the person to do. If a user submits invalid information for example, we should run tests to determine that we are providing an appropriate response to this. This may include highlighting why the information is invalid, and prompt the user to reenter something that is valid instead. I feel that the significance of “sad path” testing is to ensure that our projects are as user-friendly as possible.

The Evil Path
When we take the “evil path” approach, we ought to be putting ourselves in the mindset of a malicious actor. For instance, we should run tests attempting to infiltrate sensitive information that we expect to be secure.  I believe “evil path” testing is important because we should have our users privacy and security in mind when developing our projects.

The Weird Path
Lewis suggests that taking the “weird path” is when we look for problems that may occur beyond our control. For instance, perhaps a portion of our project needs a certain server to be active in order to function properly. In this case, we should test that our program is appropriately detecting that the server is online, and if not, perhaps we can redirect the actor to an user-friendly status page to inform the user when the server is likely to be available.

The Happy Path
Last but not least, we should test the “happy path,” which can be described as ensuring that our project is behaving as intended. If our code has a submit form for instance, we should ensure that our code is submitting the information appropriately.

My main takeaway from Lewis’ blog is that the end user (actor) does not always interact with our projects in a manner that we may expect. Rather than simply testing expected behaviors, I feel we should evaluate possible unexpected behaviors that an actor may choose to do as well. I intend on doing this during my professional career when testing future projects.

From the blog CS@Worcester – Jason Knowles by Jason Knowles and used with permission of the author. All other rights reserved by the author.

Software Tester Characteristics

This week I read a blog post from TestLodge talking about the characteristics that make up a good software tester.  The post found at https://blog.testlodge.com/characteristics-good-software-tester/ helps identify some of the attributes that a tester should have in order to be proficient in their testing as well as excel in their career.  I chose this post because it provided a different perspective than most.  As a student initially learning these skills I often get too focused on how to do different testing procedures and sometimes forget to look at why I’m doing them and what purpose do they have. Articles and posts like this help me to take a timeout and look beyond the skill set that I’m trying to acquire to help put me in the right state of mind.  The post breaks it down into 13 different characteristics.  Characteristics like testers have to be a strong communicator and be a team player.  This is good to remember, especially early on in our careers, so that we don’t ignore failed tests or improperly communicate what failed in the software to the rest of the development team and let an inferior product be released simply because we were to scared of upsetting someone by telling them part of the code is wrong.  Other characteristics like thinking creatively and paying attention to details.  These attributes will help us examine closer what the goal of the test that we need to write is and think outside the box in order to write the most effective test.  We need to be able to realize that just because we did a test a certain way in class for a project one time, that may not be the best way to write the test every time.  A good tester should also be organized and should meet deadlines.  Time management is crucial in the software development process.  Staying organized with all your tools, notes, and team communications will allow you to complete more tests.  It will also help you keep track of your deadlines and prioritize your tests so that way you are not delivering a product late of missing important tests and creating too many tests for less important features.  I felt like this post is good to revisit from time to time so that I don’t get too focused on just trying to write a perfect test and develop a broader skill set that allows me to recognize the right approach to each situation and to stay organized without rushing into a project and failing from the start.

From the blog CS@Worcester – Tim's Blog by nbhc24 and used with permission of the author. All other rights reserved by the author.

Testing Categories and Tags for Syndication

To help me with finding student’s blog posts that have been syndicated to the CS@Worcester blog, I have been asking them to tag them with the course number (e.g. CS-343). That has worked well for finding just the posts for a particular class.

But, what would make it even easier for me, would be to also have them add a tag for the week that the post is due (e.g. Week-1) so that I don’t need to scroll back until I find the first post from the previous week.

So, I’m tagging this post in the same way that I’m thinking of asking them to do it to see if it works.

From the blog CS@Worcester – On becoming an Eccentric Professor… by Karl R. Wurst and used with permission of the author. All other rights reserved by the author.

10/2/2017 — Blog assignment 3 CS 343

http://blog.synopse.info/post/2015/05/03/SOLID-Design-Principles
The topic for this week is on SOLID. SOLID stands for:
Single responsibility principle: when objects only have only 1 responsibility.
Open/closed principle: when software is opened for extension, but closed for modification.
Liskov substitution principle: when objects in a program are replaceable with instances of subtypes without significantly altering the program behavior
Interface segregation principle: when many client specific interfaces are better than one general purpose interface.
Dependency inversion principle: when one should depend on abstractions.

SOLID provides the best-practice guidelines and can help fight against 3 main code weaknesses:
Rigidity: Changes are hard since system parts are dependent upon many other parts.
Fragility: Making changes may break parts of the system.
Immobility: part of system cannot be reused in another application because it cannot be disentangled from the current application.

What I thought was interesting was the open/closed principle. Accordingly, when a class or unit is defined at the same time, it is either open for extension or closed for modification. This behavior allows existing code to be extended without breaking its initial behavior. Conformance to this policy allows for code reusability, code maintainability, and code extendibility without breaking the initial behavior of the program. An example that does not abide by this rule is a rectangle class for calculating the area of a rectangle. Say we want to extend it to calculate the area of a triangle. Then, extend it to calculate for the area of a circle. The class requires 3 different modifications. This implies that the area calculator class is not closed for modification as it needs to be changed in order to be extended, so it is not opened for extension. In large scale software development, these modifications are impractical. Instead, what would abide by this rule is a general area and shape class. This will allows for extension for the program, but its initial behaviors are closed for modifications.
The last topic that I thought was interesting was the Liskov substitution principle. The Liskov substitution principle states that if an object of type for example TChild is a subtype of another object of type TParent, then the TChild can substitute for the TParent without making major modifications to the desired properties of a program. The example presented was that of stacks and queues. If both have push and pop methods, since the storage behavior of stacks and queues are the opposite of one another they cannot inherit from a single parent type. Switching the behaviors of the stack with a queue for example will result in unexpected behavior during execution.
To adhere to this principle, the following should apply:
Class or interface definition should be properly named or commented. “behavior ” design patterns should be used when defining object hierarchy. Tests should use abstract local variables. Finally, class hierarchy should be separated.
I chose this article because it introduces one of the best practice guidelines in software engineering. For example, conformance to the open/closed policy allows for code reusability, code maintainability, and code extendibility. So, I chose it for learning purposes in order to improve coding practices for my own programs. Programming concepts for me is based on scope and visibility. Some of these programming guidelines helps create organizations in the code.

From the blog CS@Worcester – Site Title by myxuanonline and used with permission of the author. All other rights reserved by the author.